“My internet is slow” is one of the most expensive sentences a subscriber can say—not because of the call itself, but because of what it often leads to: the triage, the context-switching between systems, the truck roll that may find nothing, and the subscriber who quietly cancels a few weeks later without ever explaining why.
Churn rarely announces itself. Support calls for regional ISPs are among its earliest warning signs, signalling how an operation is structured and whether it’s built to catch problems before subscribers feel them, or only after they call. The operators who’ve cracked this distinction don’t just have happier subscribers. They have lower operational costs, less staff turnover, and a customer base that’s harder for competitors to peel away.
This guide covers the real mechanics of why support call volume stays high at regional ISPs, what actually drives churn (including the kinds that never generate a ticket), and what the path from reactive to proactive operations actually looks like.
Why Support Call Volume Stays High at Regional ISPs
The Reactive Trap
Most regional ISPs arrive at high support call volume the same way: they grow. A network that was manageable at 500 subscribers starts showing strain at 2,000. The informal knowledge that made things work, like every tech knowing every tower, AP, and quirky CPE, doesn’t scale when you’re running 30 or 40 access points across multiple counties with a mix of vendors and technologies.
The instinctive response is to add headcount. Another support rep, another field tech. But headcount doesn’t fix the underlying problem: the team is still spending most of its time reacting to issues subscribers discovered before the operator did.
This creates a specific kind of organizational friction. Support reps spend the first several minutes of every call doing triage that should have been done before the phone rang, like pulling up the subscriber account, figuring out which AP they’re on, toggling between the billing system and one or more vendor management interfaces, and trying to correlate a complaint with something measurable in the network. By the time there’s even a partial picture, the subscriber is frustrated, and the call has gone long.
This is not a training problem. It’s a visibility problem.

What’s Actually Driving the Calls
The most common inbound support call at a regional ISP is some version of “my internet feels slow” or “my connection keeps dropping.” These calls are hard to resolve quickly for reasons that don’t get enough attention.
Intermittent problems are hard to catch. A subscriber experiencing bufferbloat, where high latency under load makes a connection feel sluggish even when throughput is technically fine, may have a link that passes every basic diagnostic test. If your tools only surface throughput, you’ll close the ticket as “no issue found” while the subscriber continues to see video calls drop.
Multi-vendor environments scatter the data. A hybrid ISP running fiber backhaul into fixed wireless distribution, with CPE from two or three vendors, has subscriber data spread across systems that don’t communicate with each other. The support rep may have the billing system in one tab, a vendor NMS in another, and a speed test in a third, and still not have enough to confidently tell the subscriber what’s happening.
AP congestion is invisible until it’s severe. An access point running at 85% utilization during the evening peak may not trigger any alarms. But every subscriber on that AP is experiencing degraded quality, including higher latency, inconsistent streaming, and stuttering video calls. They’re not all calling yet, but they’re forming opinions.
The Hidden Cost of “No Issue Found”
There’s a particular kind of support ticket that does more damage than any other: the one that closes with no resolution because the problem couldn’t be reproduced.
The subscriber called, something was wrong, nobody could find it, and the ticket was closed. The subscriber remembers.
A 2025 study on fixed wireless access churn published in Telecommunications Policy found that service reliability and the quality of the subscriber relationship are among the strongest predictors of cancellation behavior in the FWA market, and that customers who experience unresolved service issues are significantly more likely to churn than those whose problems get fixed. A missed issue isn’t a neutral outcome. It’s a negative experience layered on top of the original degradation, and it tells the subscriber that calling doesn’t help.
The Gap Between Reactive and Proactive ISP Operations
What Reactive Looks Like in Practice
Reactive operations mean the primary trigger for action is a subscriber complaint. Something degrades –> the subscriber notices and calls –> the team responds. This is the default operating mode for most regional ISPs, not because operators prefer it, but because building a proactive operation has historically required visibility tools that were expensive, complex to deploy, or designed for large carriers rather than lean operators.
A reactive ISP is always behind. Resolution time starts not when the problem began, but when the first complaint arrives. This could be hours later, by which point the issue may have affected dozens of subscribers who won’t call but are quietly reassessing their options.
Reactive operations also create a confidence gap in the support team. When reps can’t quickly make sense of the network, they default to scripts: reboot the router, run a speed test, we’ll send a technician. These scripts don’t solve problems; they buy time while frustration compounds.
What Proactive Looks Like in Practice
A proactive operation flips the trigger: the tools surface problems, and the team acts before subscribers feel them or at minimum, before they call.
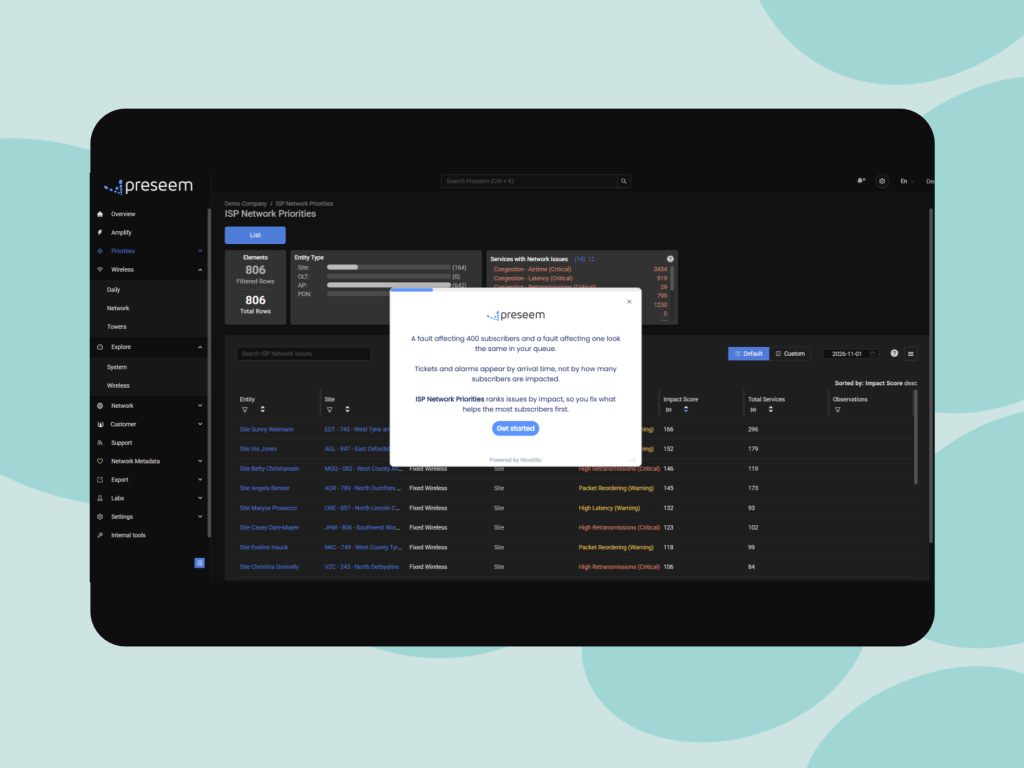
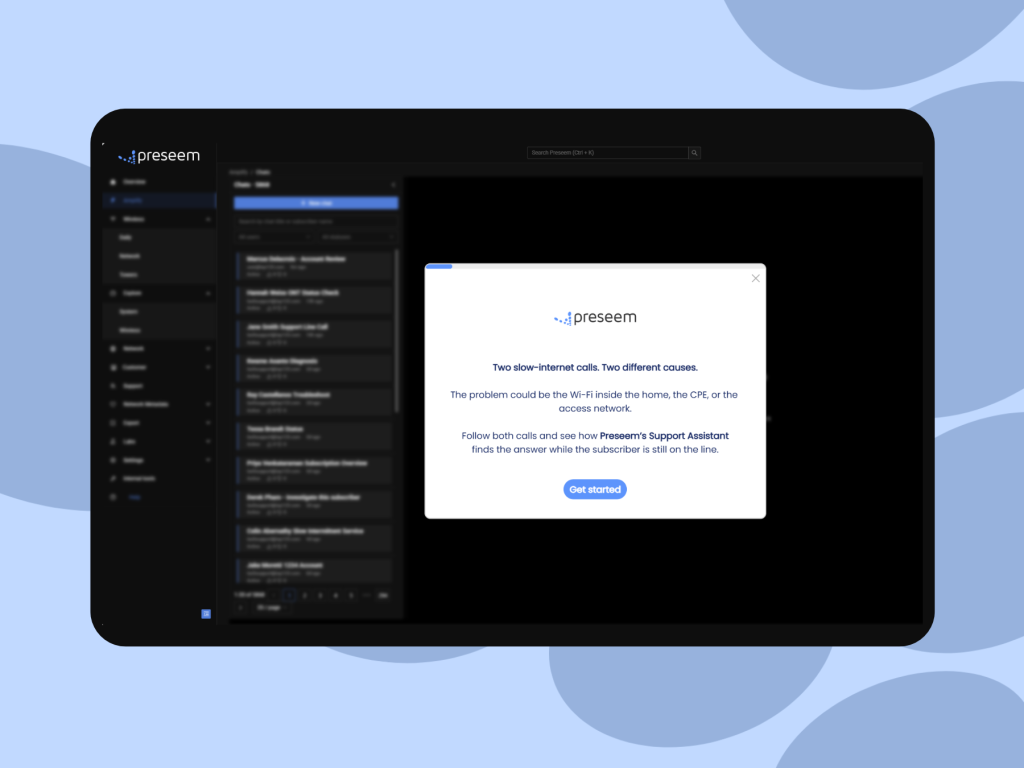
In practice, this looks like a support rep who, when a subscriber does call, already has that subscriber’s signal quality, latency history, throughput trends, and AP health visible before saying hello. The call goes from 7 or 8 minutes of triage to 2 minutes of diagnosis. Resolution rates improve. Call handle times drop. Repeat calls, one of the most expensive patterns in any support operation, fall significantly.
It looks like a network operations team that can see when an AP’s available capacity is trending toward saturation, not after the calls start coming in. And it looks like a field tech dispatched with specific diagnostic information rather than a vague symptom, who then resolves the issue on the first visit because the pre-dispatch work was already done.
The operators who make meaningful progress toward proactive operations share one characteristic: unified visibility into both the network and the subscriber experience, in one place rather than scattered across vendor dashboards and a spreadsheet.

The Subscriber Experience Problem Regional ISPs Often Underestimate
QoE Is Not the Same as Throughput
Throughput is what gets sold. Quality of experience (QoE) is what the subscriber actually feels. A subscriber on a 50 Mbps plan who experiences 180ms of bufferbloat latency during peak hours is not experiencing 50 Mbps. Their video calls drop, their games lag, and their streams buffer. The plan is technically being delivered, but the experience is poor, and they’ll eventually leave and tell their neighbors why.
Bufferbloat is particularly common in fixed wireless networks where multiple subscribers share AP capacity without intelligent traffic management. During busy hours, queues build, latency spikes, and latency-sensitive applications degrade noticeably even when raw throughput appears fine. If your monitoring doesn’t measure latency under load at the subscriber level, you don’t know how many customers are having this experience right now.
The Silent Churner Problem
Most dissatisfied broadband subscribers don’t complain before leaving. They just leave. The pattern is consistent: a subscriber has repeated degraded-experience events over two to four weeks. They don’t call, either because they tried before and it didn’t help, or because they don’t believe it will. When a competitor promotion arrives or a neighbor gets Starlink, they switch. The cancellation comes in with no explanation.
The subscribers most likely to follow this path are often on APs that are congested during peak hours but performing normally at other times. There are no open tickets, and the link is technically up. In most monitoring views, they look fine, but their evening experience is consistently degraded. Catching this requires visibility at the subscriber level, measured during peak periods, using metrics that reflect actual experience rather than link state.
Multi-Vendor Troubleshooting: A Specific Pain Point for Regional ISPs
The Context-Switching Problem
Regional ISPs who’ve grown organically, expanded through acquisition, or simply evolved over time often end up operating networks spanning multiple vendors—Cambium, Ubiquiti, MikroTik, Mimosa, Tarana, and others—each with its own management interfaces, alert formats, and data structures.
Support teams in these environments face a concrete challenge: understanding a single subscriber’s experience may require pulling information from three or four separate systems and correlating it in real time. This is slow, error-prone, and demands multi-platform fluency that takes weeks to develop and walks out the door when experienced technicians leave.
New hires typically need four to six weeks before they can troubleshoot independently. This is not a reflection of capability, but of how much institutional knowledge is embedded in the toolset rather than in a system accessible to anyone.
When support reps can see a complete, unified picture of a subscriber’s situation from a single interface, confidence improves, first-call resolution rates go up, and training timelines shrink. Staff who feel equipped to solve problems tend to stay longer, which matters when institutional network knowledge is hard to replace.
How Mascon Cut Support Call Times in Half
How Churn and Support Costs Connect to Network Operations
AP Congestion Is a Retention Problem, Not Just a Capacity Problem
AP congestion is one of the most direct and underreported drivers of churn for fixed wireless operators, and is frequently invisible in basic monitoring. An AP running over capacity during the evening peak may look healthy in periodic checks; the issue only appears under sustained load, during the hours subscribers are most actively using their connection.
Operators who reduce churn from this cause tend to do two things: measure actual available capacity at the AP level continuously across time, and use that data to make expansion or configuration decisions before the subscriber experience degrades, not in response to complaints. The goal is knowing which APs are approaching a problem threshold before the calls start coming in.
Truck Rolls: The Most Avoidable Cost in Field Operations
Unnecessary truck rolls are among the most avoidable operational costs at a regional ISP. A tech driving two hours to a site for a “slow internet” complaint that turns out to be an AP-level congestion issue that was resolvable remotely represents both a direct cost and an opportunity cost for every other issue that tech could have handled.
Better pre-dispatch diagnosis reduces unnecessary rolls, and when a truck does go out, the tech arrives with specific information rather than a vague symptom. That changes first-visit resolution rates, which matters both operationally and for how subscribers perceive the service.

The Competitive Context for Regional ISPs in 2026 and Beyond
The pressure on regional ISPs has increased materially. Starlink is a real competitor in rural markets, particularly for subscribers with persistent unresolved service issues. BEAD-funded fiber overbuilding is expanding into markets that have historically been fixed-wireless-only, and national carriers’ fixed wireless offerings continue to mature.
The primary competitive advantage available to a regional ISP is service quality and the subscriber relationship. Subscribers who have genuinely good experiences don’t leave for alternatives. As WISPA’s VP of Government Affairs told operators at WISPAmerica: “AT&T, T-Mobile, all the major cable providers, the satellite industry — they’re all looking at you. When I started in this industry 15 years ago, they weren’t looking at you.”
Preseem’s ISP Network Report benchmarks annual churn under 3% as the target for a healthy operation, and finds that operators who actively measure subscriber experience consistently score well above average on customer satisfaction.
Download the 2026 ISP Network Report
What a Proactive Operations Model Requires
Getting from reactive to proactive doesn’t require enterprise-scale infrastructure. But it does require specific operational capabilities that many regional ISPs currently lack.
Subscriber-level QoE visibility. Per-subscriber metrics for throughput, latency under load, and signal quality—tied directly to the network topology—so you can trace a QoE problem to its root cause without jumping between systems.
Unified data across vendors and technologies. If your support team navigates three different interfaces to understand a single subscriber’s situation, every call is slower and more error-prone than it needs to be. Unifying that data across access technologies, CPE vendors, and back-office systems is foundational to both support efficiency and proactive monitoring.
Continuous AP capacity monitoring. Periodic snapshots miss the peak-hour patterns that drive subscriber dissatisfaction. You need utilization data covering busy hours consistently, so you can identify congestion before it produces churn.
Alerting that precedes complaints. The operational difference between reactive and proactive often comes down to whether your alerts fire before or after the subscriber calls. Alerts on subscriber-level QoE degradation and AP capacity thresholds, rather than just link state, give your team the window to act first.
Fast deployment, low overhead. Tooling that requires network redesign or months of implementation rarely gets deployed. Platforms that deliver actionable data quickly, without complex routing changes, have a fundamentally different ROI profile for a regional ISP.
How Preseem Helps Regional ISPs Move from Reactive to Proactive
When your subscribers are having bad experiences, you’re often the last to know. That’s the problem Preseem is built to solve. Competitors are growing, budgets are shrinking, and teams are doing more with less. The operators who stay ahead are the ones who stop waiting for subscriber complaints to surface network problems.
Preseem’s award-winning platform gives ISPs proactive intelligence to act before issues escalate. For support teams, that means faster resolution and shorter training timelines. For network operations, congestion and QoE degradation surface before subscribers feel them. For leadership, churn risk is visible and addressable rather than invisible until a cancellation appears in the billing system.

See Preseem in Your Network
Frequently Asked Questions
What are the most common reasons support calls for regional ISPs stay high?
The primary drivers are reactive operations, limited per-subscriber QoE visibility, multi-vendor environments that scatter diagnostic data, and AP congestion that produces intermittent degradation during peak hours. Each compounds the others: intermittent problems generate repeat calls, multi-vendor setups extend handle times, and congestion produces complaints that are hard to diagnose without granular data.
How does reducing support calls relate to reducing churn?
They’re linked but not the same problem. Unresolved support interactions are among the strongest predictors of churn. But many churning subscribers never call. They experience repeated degraded-QoE events, decide the service isn’t worth it, and leave silently. Reducing churn requires both resolving calls more effectively and detecting degraded subscriber experience proactively, before the cancellation decision is made.
What does “proactive network management” mean for a regional ISP in practice?
It means your team learns about problems before subscribers call. In practice: knowing when AP capacity crosses a threshold rather than when complaints arrive; subscriber-level QoE visibility that lets reps understand a caller’s situation before picking up the phone; and continuous peak-hour monitoring that identifies degraded subscriber experience before those subscribers reach the cancellation decision.
Can a small ISP with limited staff realistically benefit from QoE monitoring?
Often more so than large operators. A support team that resolves calls in half the time and eliminates a portion of inbound volume through proactive detection effectively operates at significantly higher capacity. The reduction in truck rolls, repeat calls, and re-work compounds quickly in a lean operation.
What’s the difference between throughput monitoring and QoE monitoring?
Throughput monitoring tells you how much data is moving across a link. QoE monitoring tells you what the subscriber actually experiences, i.e. whether latency is high under load, whether the connection feels responsive, whether latency-sensitive applications like video calls and gaming are performing well. A link can pass a throughput test while delivering a poor subscriber experience due to bufferbloat. QoE monitoring surfaces what throughput monitoring misses.
Why is multi-vendor troubleshooting such a significant challenge for regional ISPs?
A single subscriber’s diagnostic picture may be spread across a billing system, vendor NMS platforms, a backhaul monitoring tool, and a ticketing system. Support reps must manually correlate all of it in real time on a live call, adding minutes per call, requiring substantial training, and creating knowledge dependencies that leave when experienced staff do.
How does AP congestion cause churn if subscribers aren’t always complaining about it?
Congested APs degrade QoE during peak hours while performing normally off-peak. Subscribers experience the problem when most engaged with their connection but often don’t report it because previous attempts didn’t produce results. They remain on the account until a competing option appears, then cancel without warning. Accounts with no open tickets and no alarms can still carry significant churn risk.
Is Starlink actually a competitive threat to regional fixed wireless ISPs?
It has become one, particularly for subscribers with persistent unresolved service quality issues. Starlink’s latency and performance have improved significantly and its rural availability is near-universal. The most effective defense isn’t price matching, it’s consistently better QoE and a support experience that resolves issues. Operators running proactive operations retain those subscribers rather than losing them before the problem surfaces.