How Netflix Works – Technical Webinar Recap

How Netflix Works: Webinar Recap

Preseem recently held a webinar where our co-founder and Chief Technical Officer Scot Loach explained how Netflix works, why it’s not a stream, and why your ISP should prioritize managing the network and not individual applications.

(Some of the content in the webinar and this recap article was covered in a previous blog post—consider this an update and expansion on that information.)

We chose Netflix specifically as our focus for the webinar in part because of its sheer dominance. According to Sandvine’s 2022 Global Internet Phenomena Report, Netflix accounts for close to 21% of the total volume of internet traffic, followed by YouTube (15.9%) and Facebook (7.8%). However, if you look at peak hours, reports have Netflix as high as 40% of total traffic on some networks.

Chart showing most used applications on the internet

We also chose it because we have some unique expertise with Netflix thanks to a previous (pre-Preseem) product we made named NightShift. This was an in-home Netflix cache designed to reduce usage of the internet during peak hours and to help people binge their favorite Netflix shows without buffering.

During the development and deployment of that product, we learned a lot about how Netflix works and believe it’s important to pass that knowledge along to ISPs, given the application’s popularity and effect on networks.

How Does Netflix Work?

So, what is actually going over the network when a Netflix video is played?

Netflix has been streaming video since 2007, since which the industry has evolved greatly (new devices, new hardware, advances in video encoding technology). All the newer encoding standards do a better job of compressing video, but Netflix still has to operate on devices with older standards as well.

Because of this, every title on Netflix has to be encoded in each container format. As well, each title is encoded to a different ‘bitrate ladder,’ because different devices can play video at various resolutions. Resolutions also vary, because some plans won’t support higher resolutions or a network might not be able to support them during peak congestion periods.

Charts showing Netflix bitrate ladders and resolutions

Netflix now also encodes separate chunks or segments of videos at different levels, e.g. three minutes at a time. The reason for that is some videos are easier to compress from frame to frame than others. For example, a cartoon can be compressed to a lower bitrate compared to an action movie. As a result, there’s really no correlation between the bitrate of a video being played and its quality or resolution.

Netflix is Not a Stream

This is covered in our previous blog, but it’s important to reiterate that streaming video on Netflix is not a stream at all. It’s actually a file download, just like any other big file being downloaded. How Netflix works is that files are downloaded into a buffer chunk by chunk. When your player (e.g. TV, phone, PC) is playing a video, it’s just taking the next data segment of the video from an internal buffer, decoding it, and putting frames on the screen for you to watch. What’s interesting is how the buffer is filled from the network.

Netflix downloads chunks of content into a buffer.

When a subscriber starts playing a video, their player device authenticates with Netflix. This way, Netflix knows who they are and what plan they’re on, as well as the type of device and the resolution its capable of playing. Netflix then sends a manifest file, which has the bitrate ladder and a list of three URLs for each bitrate that the player can visit to download the video. URLs are chosen based on the Netflix CDNs that are closest to the subscriber.

The player then selects a resolution from the bitrate ladder, connects to the CDN nodes, downloads video from each, figures out which it likes best, then downloads the video chunks into the buffer. Video is downloaded using HTTP over TLS, which means the video downloads are encrypted and can’t be inspected on the wire. This means only the player and the server knows the content, resolution, and codec.

Where Netflix Traffic Comes From

Netflix traffic actually comes from many different places, such as a variety of ISPs and internet exchange points close to the client watching a video. The company has an Open Connect cache farm that ISPs can qualify to take part in. Netflix will then actually ship OC servers and provide the content. The ISP’s subscribers in the area then get their Netflix from those caches. Check out their Open Connect site for more information.

Netflix downloads chunks of content into a buffer.

How Netflix Uses Buffers

Netflix uses a large buffer (almost five minutes of video) that allows it to handle network outages or degradations without it interrupting the user experience. If the throughput goes below the level of the video for a while, Netflix will start a new buffer lower on the bitrate ladder and start loading the buffer with the lower-bitrate video. The playing bitrate will then change to the lower-bitrate video, called a ‘downshift.’ The opposite can happen as well to upshift the buffer to a higher bitrate. The exact details of how this is done are proprietary to Netflix.

It’s important for ISPs to know this, especially if they’re using bandwidth bursting, as it could cause Netflix to misestimate the throughput when a video starts.

The image below shows three TCP flows being used to deliver video to a smart TV in a real experiment conducted by Scot. This shows how Netflix is not a stream but a download. It’s not streaming at a fixed bitrate of 6Mbps—it’s actually doing 40Mbps early on to fill up the buffer, then zero for a while as it plays some of the buffer, then spiking between 15-25Mbps and zero over time as it downloads segments to keep the buffer full. From there, it divides pretty equally between the three flows to keep the buffer topped up.

Netflix uses multiple TCP flows to maximize the buffer fill speed.

Based on some other experiments Preseem did, we found that different players have different behavior. An Android phone might typically use one flow per stream, for example, while a PC browser will use three.

The Myth of Managing Netflix

What does all this mean for network management policies and QoE management? For one, it explodes the myth that network policy can control video resolution.

Using the example in the image below, imagine your ISP wanted to use a tool like Deep Packet Inspection (DPI) to set and enforce a policy where, during peak hours, subscribers only get 1080p. DPI gives you two tools for this: a per-flow bitrate cap and an overall per-user bitrate cap. Let’s look at both options.

Per-flow: In the example on the left below, this 12 Mbps streaming video has three flows, so maybe if you set a 3Mbps per-flow limit, it could restrict it to 1080p instead of playing in 4K. In the example on the right, however, the 3Mbps per-flow limit will be fine for mobile devices but will severely downgrade the quality for the TV watcher below 1080p. As a result, you haven’t delivered the experience that your policy promised.

Per-user: Alternatively, imagine you’ve set a limit of 8Mbps total, which should be enough for a 1080p stream. In example 1, this will split each flow into about 2.5 Mbps, and that should be OK. But again, in the second example with multiple devices, the TV flow will definitely be below 1080p and the mobile devices will also struggle to get to their 720p resolution.

Netflix uses multiple TCP flows to maximize the buffer fill speed.

These are just examples, but any vendor that tells you that you can restrict Netflix playback to a specific resolution is telling you something that’s not possible. You can’t control the resolution that your subscribers will experience, and you also can’t control the number of concurrent streaming sessions that they’ll get.

Using DPI for QoE is No Longer Relevant

Because of the way Netflix works—e.g. running at 40 Mbps to fill the buffer when video playback begins—it can have a huge effect on other protocols that are running concurrently, at any point of congestion (e.g. the user self-congesting or upstream at an AP).

An older workaround for this would be to use DPI and configure it to limit Netflix during peak hours so that there’s room for other traffic. The main problem, however, is that there’s really no way to know what that limit should be. You don’t know what the variable bit rate encoding will be, how many concurrent streams, etc.

The secondary issue is an overall problem with DPI. It uses application signatures to identify traffic, and these can be brittle. As applications change the signatures have to be updated, for example, or as new applications appear signatures have to be added.

TLS 1.3 is a Problem for DPI

DPI can recognize Netflix today because Netflix’s signatures haven’t changed in a decade. With the coming introduction of TLS 1.3, however, that may change due to encryption that would make it possible to send traffic with no way to identify it. In the near future, Netflix and other streaming services may become much harder to detect.

For example, consider the Sandvine report we referenced at the start of this blog. “Unknown QUIC” is #4 on their list of internet volume—that’s traffic that hasn’t been identified but which could well be Facebook or YouTube or some other popular app. However, all they can identify is the protocol it’s using.

There’s a trend toward greater privacy and greater encryption. If and when major applications like Netflix and Disney Plus adopt TLS 1.3, DPI will no longer be able to definitively identify them.

So how to prevent Netflix from taking all your capacity? The solution lies with Active Queue Management (AQM) using FQ-CoDel/Cake. This solves the problem of one protocol crowding out others. With AQM, everything gets its fair share of the network, so that traffic feels fast even when queues are full. This is the way of doing network management in the 2020s to solve this problem.

TCP Proxies (Acceleration) Can Impair QoE

Like DPI, TCP Proxies (Acceleration) are a traffic management technique whose usefulness is fading. TCP Proxies can fill the buffer faster, but at the expense of other protocols such as UDP traffic like gaming, web browsing, and VoIP (not to mention YouTube and Facebook video streams that use QUIC/UDP).

Netflix uses multiple TCP flows to maximize the buffer fill speed.

This leads to congestion within the home and across subscribers sharing an AP. Netflix has its own algorithms for dealing with network congestion, such as their large client-side buffers and the resolution ladder shifts mentioned above. As a result, ISPs don’t really need to do anything extra to help Netflix have a lot of the network. Netflix will also likely migrate to QUIC/UDP as HTTP3 becomes standard, so TCP Proxies will become even less helpful.

Manage the Network, Not the Netflix

To summarize, the main message here is to manage the congestion, not the application. Here’s why:

  • Netflix uses multiple TCP connections and uses TLS, so it’s not possible to limit the number of devices or streaming sessions
  • Videos from Netflix are variable bitrate encoded, so it’s not possible to limit resolution/video quality with network policy
  • Netflix downloads in short bursts at full link rate, which can negatively impact other traffic—AQM prevents this from using more than its fair share of the network

Artificial reduction in capacity is a mitigation of the problem, not a solution. Proactively managing capacity to deliver more bits to the customer is your best bet at providing a great experience. Networks that are optimized for particular applications or worse, particular transport protocols, are very brittle going forward. Instead, use AQM to maintain a clean network that’s fair to all protocols and provides the best QoE, and let Netflix self-adjust to network congestion using its own algorithms.

Watch the full webinar below!
Where Do the Minutes Go on a Tier 1 ISP Support Call?

A subscriber calls because the internet has been dropping out every evening, and your agent starts the call already behind. They open the account in billing, then the subscriber's radio or ONT in the vendor's portal, then the ticket history, and run a test against the CPE while narrating the wait to someone who was already annoyed when they dialled. That's often how a technical call runs in Tier 1 ISP support: much of it goes to searching, and the conversation fits in around it.

A seasoned agent knows which systems to open and in what order, but still has to open them, because the subscriber's experience, the state of the shared asset and the history of the account are stored in different places. As Wi-Fi or the Network? set out, each check answers part of the question and sends the agent somewhere else for the rest, so the difficulty lies in where the evidence lives rather than in the person reading it. When the call runs out before the answer arrives, the subscriber gets a callback, an escalation or a reboot script that may not address the fault.

Why Is One Agent Doing Two Jobs on Every Call?

Every technical call holds two jobs. One is finding the answer: gathering evidence across systems, comparing this subscriber with their neighbours and deciding where the fault is. The other is handling the person: listening and empathizing with what they've been living with, explaining what's wrong in terms they recognize and telling them what happens next. They're different skills, and on today's desk one agent does both at once.

On the evening-dropout call, the investigation takes the agent's attention first, because there's nothing to explain until it's done. The subscriber listens to typing while the agent moves between portals, and if the answer arrives after they've hung up, the explanation never happens, and the ticket moves to Tier 2. Repeated across a day, that's the reactive load that keeps ISP support teams stuck in firefighting mode.

What Does Tier 1 ISP Support Need on Screen to Close the Call?

Four pieces of evidence, read together:

The What Tier 1 Needs

Where It Usually Lives Today

What It Helps Determine

The What Tier 1 Needs

The subscriber's experience over the window they're describing (latency, packet loss, throughput against their plan)

Where It Usually Lives Today

A QoE system, if the operator collects it at all

What It Helps Determine

Whether the problem the subscriber describes actually happened, and when

The What Tier 1 Needs

The asset they sit on, and how other subscribers on that AP, sector or PON did over the same hours

Where It Usually Lives Today

The network management system, or one portal per radio and OLT vendor

What It Helps Determine

Whether others on the same asset were affected at the same time, which points to a shared issue

The What Tier 1 Needs

Has a problem that's in your network

Where It Usually Lives Today

The radio or OLT vendor's tool

What It Helps Determine

Whether the drop to the home is healthy, which narrows the search without placing the fault inside the home

The What Tier 1 Needs

What was tried on this account last time

Where It Usually Lives Today

The ticketing system or CRM

What It Helps Determine

Which steps not to repeat

None of these settles the question alone. Identifying an in-home Wi-Fi problem takes evidence from behind the CPE, and neighbours degrading at the same hours points to a shared issue without naming its cause. With all four in one view, an agent can reason through the diagnosis and explain what the evidence points to as they go, but reading them together mid-call is still the investigation, just done faster.

How Does an AI Support Assistant Get the Answer on Screen?

Preseem's Support Assistant, part of Preseem Plus, does the troubleshooting itself. Once the call is tied to a subscriber, it works through the same evidence an agent would chase across systems: the subscriber's experience over recent days, the other subscribers on their AP, sector or PON, the history of their radio or ONT, and the tickets already on the account. It gives the agent the cause and the next action in plain language, including whether the fault is in the home or on the network, and where, along with the evidence that places it there.

On the evening-dropout call, the agent opens the account and sees the pattern laid out: the subscriber's latency and packet loss climbing from around 7 p.m. on each of the evenings they described, their radio link healthy throughout, the other subscribers on the same sector showing the same pattern over the same hours, and the sector running at capacity while it happens. The assistant reads those together and places the problem on the shared sector as evening congestion, then routes it to the network team with that evidence attached. That reading is what it adds beyond four sources on one screen, since the agent isn't the one left to work out whether a healthy link and degraded neighbours add up to congestion.

The agent doesn't need another round of checks; they square the answer with what the subscriber is describing and act on it. Because the Support Assistant works alongside the agent, a person who knows the subscriber and the network sees its answer before the subscriber does, which is what separates an assistant from a tool placed in front of the subscriber, as covered in what AI actually does in ISP customer support.

What Does the Agent Tell the Subscriber?

With the investigation done, the rest of the call focuses on the subscriber. The agent can tell them that their own connection and equipment are fine, that the slowdown they've been seeing is on the part of the network they share with their neighbours and happens when it's busiest in the evening, and that it has been escalated to the network team with the evidence attached. Then comes what happens next: when they should see a change, that nobody needs to visit, and how they'll hear back.

The agent also has time to listen. If the subscriber mentions that the dropouts happen on weekend mornings too, that doesn't fit an evening congestion pattern, and an agent who isn't juggling portals can hear it, ask about it and check it against what's on screen before the call ends.

How Much Shorter Do Calls Get When Tier 1 Has the Answer?

Among Preseem customers using the Support Assistant, we've seen call times fall from over 30 minutes per call to under five. Read it as an indication of what's possible rather than a benchmark for your desk; your own call mix and network will shape where you land.

What Happens Next Once Tier 1 Has a Diagnosis?

A diagnosis on the call leads to one of three outcomes, and only one resolves the issue before the subscriber hangs up. When the assistant places the fault inside the home, the agent can often fix it with the subscriber on the line by moving the router or switching a device to a wired connection. Where the home network itself is what's holding the subscriber back, such as an ageing router or Wi-Fi coverage that doesn't reach the rooms they use, the agent can also offer a managed router service, so the operator looks after that part of the connection from then on. When it points to a fault on the shared network, as on the evening-dropout call, the ticket goes to the NOC with the fault confirmed. When it points to the subscriber's own link, a technician goes out with the fault already located.

The second and third outcomes still leave work for someone else, but they change what that work is. A call that runs out before the cause is found often escalates as little more than a description of symptoms, and Tier 2 or a network engineer starts the investigation again from scratch. With the diagnosis and its evidence attached, they start from the finding, and that's the metric for a support leader to watch: how many tickets reach Tier 2 needing the investigation started over. The engineers who would otherwise rerun it are often the same people planning upgrades and building out new areas, so each investigation they don't repeat is time back on that work. For how this fits with first-contact resolution, ramp time and the rest of the desk's numbers, see the complete guide to improving ISP support performance.


Take A Tour:

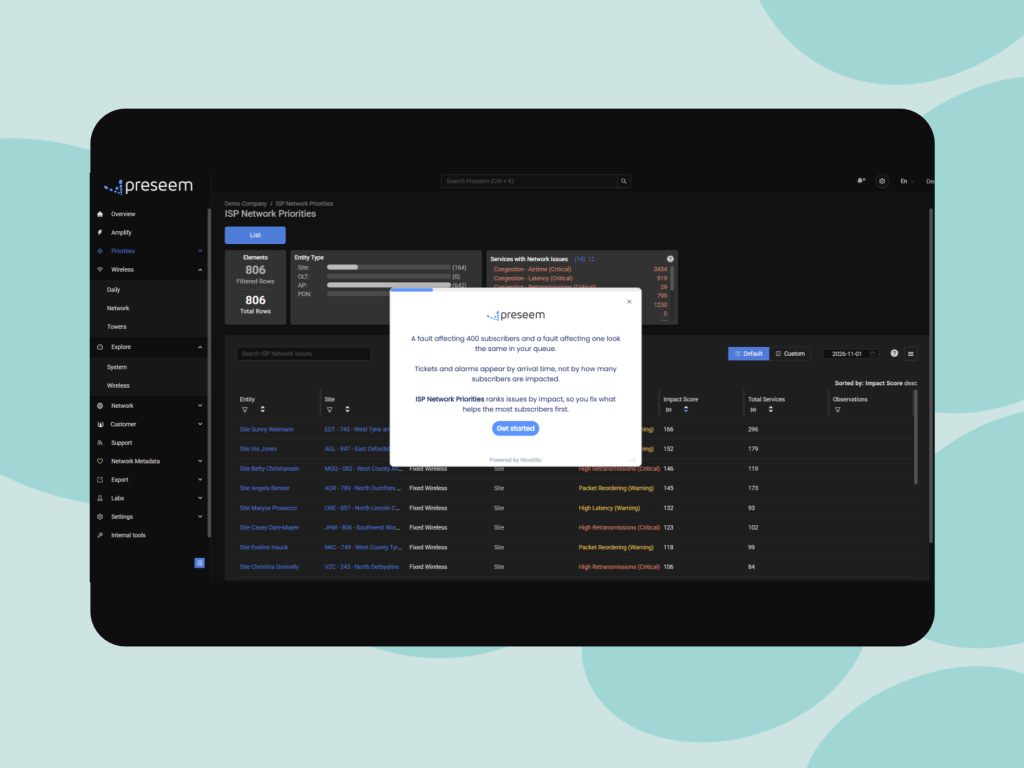
ISP Network Priorities

Explore how Network Priorities ranks network issues by subscriber impact, helping you focus on the fixes that make the biggest difference.

Take A Tour:

Support Assistant

See the Support Assistant in action! 

Frequently Asked Questions


When should a Tier 1 ISP support call escalate?

A call should escalate when the fix needs something Tier 1 can't do: a configuration change on the network, a field repair, or a fault the NOC has to work. An escalation made because nobody could identify the cause in time is the easiest kind to recover, since the information needed to settle it often already exists in the operator's systems. Sort a month of escalations into those two groups and you'll see how much of your Tier 2 load is diagnosis rather than repair. The ISP support performance guide covers the escalation measures that sit alongside it.

Is an AI support assistant for ISPs just a smarter knowledge base?

No. A knowledge base holds procedures that apply to any subscriber, while an assistant connected to network data works out what's wrong with this subscriber's connection today. The knowledge base still has a place, because it's where the steps for a router reset or a plan change live once the cause is known. What it can't do is locate the fault, which is why an agent working from articles alone ends up troubleshooting by elimination.

What does AI agent assist need from a broadband network?

It needs per-subscriber experience measured continuously, a map tying each subscriber to the AP, sector or PON they sit on, access-link telemetry from the radio and OLT vendors you run, and the account's ticket history. To place a problem inside the home rather than just rule out the access link, it also needs evidence from behind the CPE. The topology map is easy to overlook, and without it a tool can't compare a subscriber with their neighbours, which is how a shared fault is told apart from a single one.

What if the subscriber doesn't accept the help desk diagnosis?

Show them the evidence in terms of their own experience: the drops on the evenings they described, or the fact that their neighbours on the same sector saw the same thing. A help desk diagnosis is much easier to accept when it matches what the subscriber lived through, and an agent with the answer already on screen has time to make that connection instead of reading a conclusion off a script.

About Preseem

Preseem shows regional ISPs what every subscriber is actually experiencing, from the network into the home and across every major equipment vendor. Operators use it to improve subscriber experience and business results together: keeping subscribers happier for longer, running a more efficient operation at lower cost, and earning more from upgrades and services subscribers want. Preseem turns that intelligence into next steps for support, the NOC and sales, aimed at whatever helps the most subscribers. Support Assistant gives the rep on the call the cause and the next action in plain language, including whether the fault is in the home or on the network. Network Priorities ranks the sites, APs and PONs to fix first by how many subscribers each one is degrading, and Service Priorities shows which subscribers to contact and whether to fix something or offer an upgrade. Expert view keeps two years of history behind every subscriber, AP and OLT. Learn more at preseem.com.

[/et_pb_post_content][/et_pb_column][/et_pb_row][/et_pb_section]

Latest From Our Blog

Network insights, best practices, and product updates to help you get the most from Preseem.

STOP MANAGING COMPLEXITY

START RUNNING YOUR BUSINESS

Every week without visibility is another week of trucks that didn't need to roll and subscribers who left without telling you why.

Let's start with your network, your vendors, your subscribers.